


BluePes Blog: Insights & Trends


AI agents in production: controls that stop runaway runs
What follows is why agents run away, the specific controls that stop them — per-step and per-run timeouts, retries with backoff and idempotency, token and cost budgets, loop detection — and when escalating to a human beats retrying one more time.
- Nov 06, 2026
- 16 min

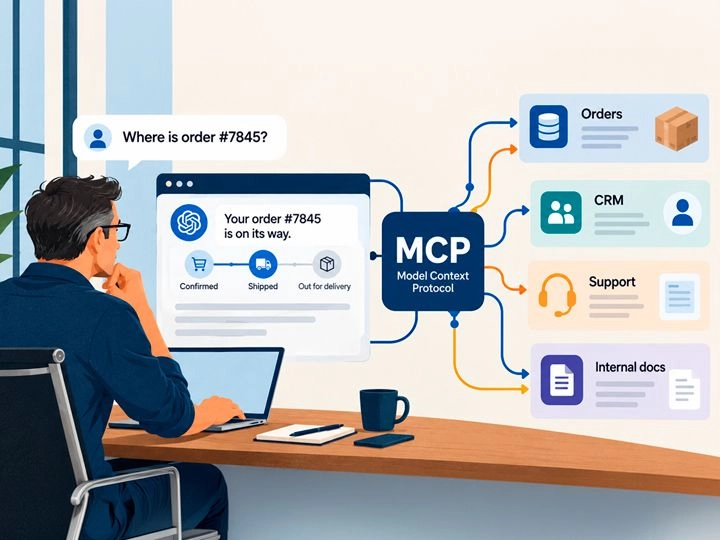
MCP integration: connecting AI to the data it needs
What follows explains what MCP standardizes, how tools and resources differ, how to design scoped access with approval gates, and where these integrations tend to break once real traffic and real permissions are involved.
- Oct 30, 2026
- 16 min

LLM cost optimization: controlling tokens and model choice
What follows maps where the cost accumulates, which controls reduce it without hurting answer quality, how to choose between caching, routing, and batching, and the instrumentation you need before changing anything in production.
- Oct 23, 2026
- 16 min

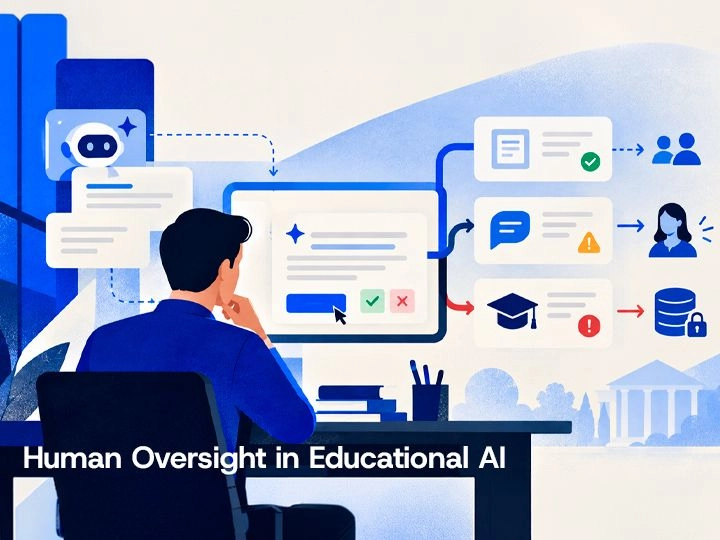
Human-in-the-loop AI in EdTech: where review belongs
The engineering question is therefore where human judgement enters the state machine and what authority that person actually has. A credible design defines review states, reviewer permissions, audit events, exception handling, and queue behavior before production traffic arrives. That lets an EdTech team protect higher-risk decisions without turning every suggestion, classification, or draft into a manual bottleneck.
- Oct 16, 2026
- 16 min

When an AI agent does something it shouldn't: approval gates and blast-radius limits
You can give an agent real authority without betting the business on its judgment. Grant it the minimum tools and access its job needs, require a human to approve anything irreversible, and cap what any single action can touch. Log every action with its reason, so a mistake stays visible and undoable.
- Oct 09, 2026
- 16 min

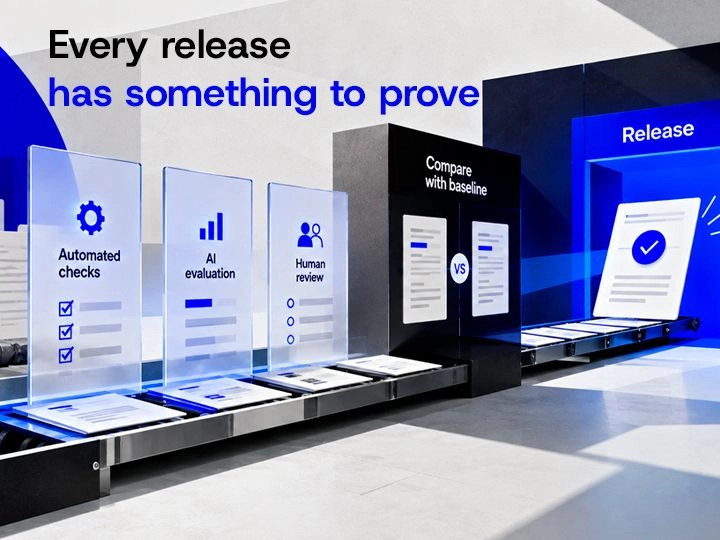
AI testing in EdTech: how to catch regressions before launch
The prompt change fixed the support assistant’s bad answer on Tuesday; by Friday, the same release had broken citation accuracy in cases nobody retested. AI testing in EdTech has to catch that kind of regression before users discover it. A conventional test suite can confirm that APIs return 200 responses and schemas remain valid. The generated answer can still become less accurate, less complete, or less grounded after a model, prompt, retrieval, or data-source change.
- Oct 02, 2026
- 16 min

Confident, wrong answers: fixing retrieval before you blame the model
A wrong answer from an AI assistant would be easy to catch if it looked unsure, and it never does. Three colleagues forward the same screenshot: the internal assistant answered a policy question with complete confidence, and it was wrong. After a few of those, people stop asking it and go back to messaging each other.
- Sep 25, 2026
- 16 min

EdTech Data Architecture for AI Across Education Systems
The practical question is therefore wider than “How do we connect the SIS to the LMS?” A CTO or product lead needs to decide which system owns each entity, how standards fit the integration surface, how local mappings are versioned, and what the platform should do when sources disagree. Those decisions determine whether AI receives usable context or merely collects more contradictions.
- Sep 19, 2026
- 16 min


Adding an AI feature to a live product without a rewrite
The pattern below is how experienced engineers move an AI feature from demo into production. It also marks where that path tends to break.
- Sep 11, 2026
- 16 min